 Private AI on Your Own Hardware
AI that runs in your office, on hardware you own.
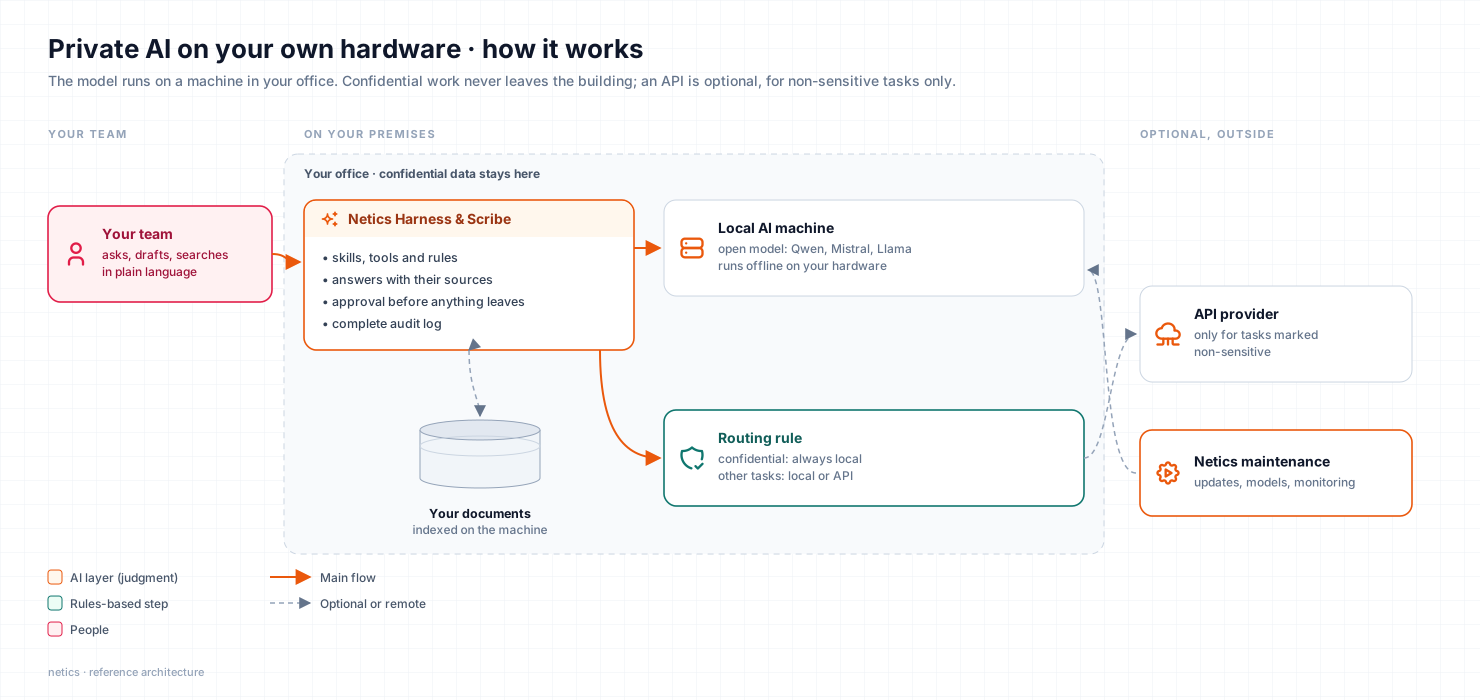
We size, install and maintain the machine that runs your AI on site: a compact Mac mini for a small team, an AMD or NVIDIA machine for heavier work, up to a Mac Studio for the largest open models. Your documents stay in the building, and Netics Harness and Scribe run on top.
What's included
Hardware Sizing & Consultation
We match the machine to your models, users and budget, with the honest trade-offs: memory, speed, noise, power and price.
Local Model Setup
Open models such as Qwen installed, quantized and tested on your hardware, then connected to Harness, Scribe or your own tools.
Maintenance Contract
Updates, model upgrades, monitoring and backups for your AI machine, for a fixed monthly fee.
Hardware we set up
We size each machine to your models and users. Hardware and models change fast, so we recommend a configuration at the start of each project.
Mac mini
- Memory
- Entry configurations
- What it runs
- Small and mid-size open models
- Best for
- A quiet office assistant for a small team
Mac mini with a Pro chip
- Memory
- More unified memory
- What it runs
- Mid-size open models such as Qwen, at a comfortable speed
- Best for
- A private document assistant for a team
AMD Ryzen AI mini PC
- Memory
- Large unified memory
- What it runs
- Mid-size models fast, very large models at a slower pace
- Best for
- A lot of memory for the budget, Linux friendly
NVIDIA DGX Spark
- Memory
- Large unified memory
- What it runs
- Large open models with the full NVIDIA software stack
- Best for
- Teams that also fine-tune their own models
NVIDIA RTX workstation
- Memory
- Dedicated GPU memory
- What it runs
- The fastest answers on mid-size models
- Best for
- Many users at the same time
Mac Studio
- Memory
- Very large unified memory
- What it runs
- The largest open models, entirely on site
- Best for
- Everything stays in the building, at full scale
Works with
- Apple
- NVIDIA
- AMD
- Ollama
- Hugging Face
- Qwen (Alibaba Cloud)
- Mistral AI
- Meta Llama
- DeepSeek
A good fit if
- Your documents must stay on your premises
- You prefer a fixed hardware cost to a growing API bill
- Your AI has to keep working offline
Related solution
 Netics HarnessYour own AI agent platform. Any model, your rules.
Talk it through with an engineer
Thirty minutes to look at your situation and what would help. You leave with a clear next step, whatever you decide.