 Netics Scribe
Ask your documents and get sourced answers.
Scribe answers questions from your own documents: procedures, contracts, product documentation, internal knowledge. It runs on infrastructure you control and points to the passages its answers come from.
The problem
Knowledge is scattered across folders and people's heads. The same questions get asked again and again, and generic chatbots don't know your business while sending your data elsewhere.
How it works
Connect your sources
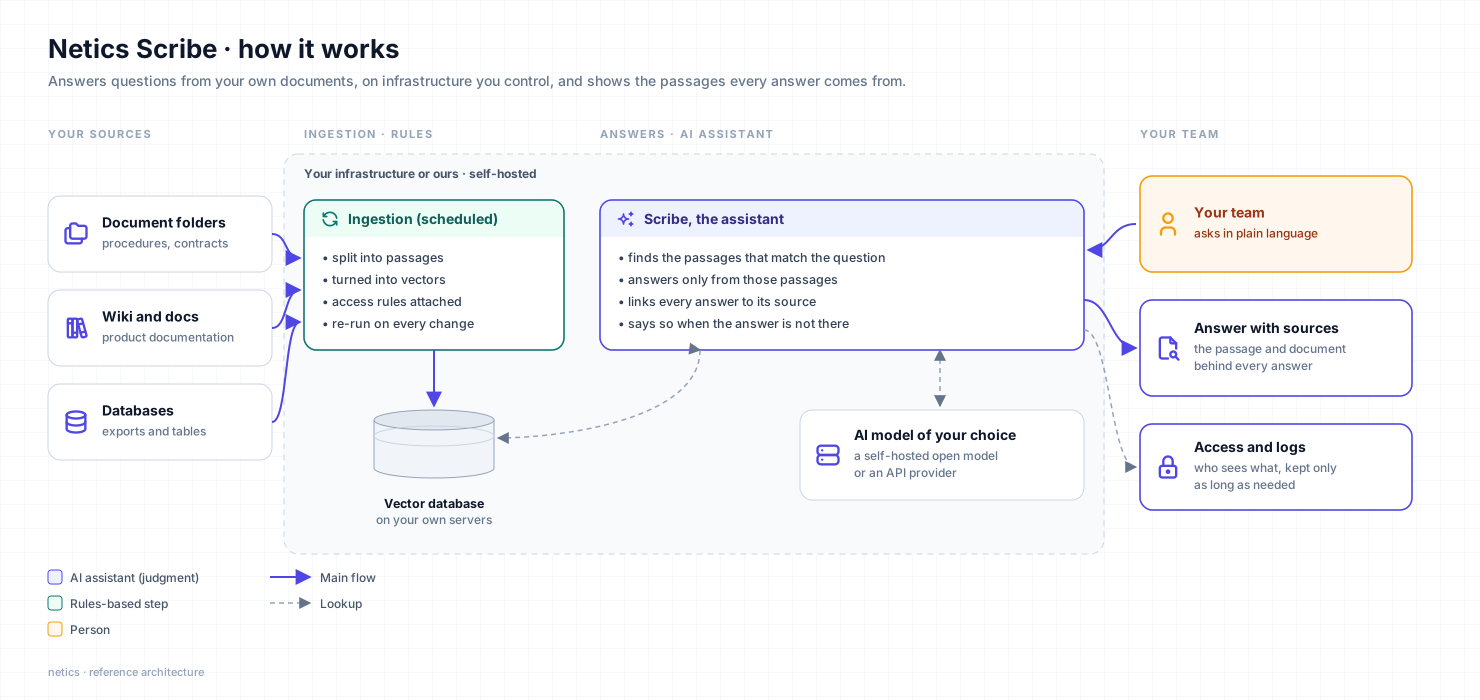
Document folders and knowledge bases, synchronised on a schedule.
Index
Documents are split, converted into searchable vectors and stored in a database on your servers.
Answer
Each question retrieves the most relevant passages, and the AI answers from them with references.
Keep it current and controlled
Automatic updates, access rules and logs kept only as long as needed.
What you get
- An assistant as a web widget or internal chat
- An ingestion pipeline with automatic synchronisation
- Retention and privacy settings configured
- An administration guide
Built with
n8n, Qdrant, embeddings, an AI model of your choice: self-hosted open models or an API provider
A good fit if
- Your team searches the same documents every day
- Answers must stay consistent with your official documentation
- Your documents must not leave your infrastructure
The assistant on this website works this way: our documentation lives in a self-hosted vector database queried on every question. The public demo uses an external model provider; client deployments can run entirely on self-hosted models so documents never leave your infrastructure.
Talk it through with an engineer
Thirty minutes to look at your process and whether this fits. You leave with a clear next step, whatever you decide.